AI for Chess Coaches: Division of Labor
AI for chess coaches, one week at a time: Stockfish evaluates, the model drafts, records supply the numbers, and a named human approves every send.
By Abhishek Tiwari · Published June 10, 2026 · Updated October 2, 2026 · 20 min read
Bottom line
AI for chess coaches comes as named tool types: player-facing AI coaches such as BetterChess Club, which gives each club student coached practice between sessions [7], and academy management software such as ChessCore, whose AI copilot drafts reviews, reports and reminders that wait for a coach to approve [10].
TL;DR
- Player-facing AI coaches such as BetterChess Club give students coached practice between sessions [7]; ChessCore's AI copilot drafts the academy's game reviews, reports and reminders, Stockfish judges every position, and drafts wait in one queue until a coach or admin signs off [10].
- Stockfish evaluates positions deterministically; the language model only writes the narrative around evaluations and numbers it is handed.
- Every figure in an AI draft, including attendance counts, fee amounts, and ratings, should be injected from database records the model cannot edit.
- No AI-drafted message should reach a parent or student without a named human approving it first, which is also what the NIST AI Risk Management Framework calls for.
- Mapped onto a real coaching week, this framework removes the writing bottleneck while leaving every judgment call with the coach.
Key facts
- BetterChess Club lists $99 per month for 25 student seats, extra seats at $3 per month, a free coach account, and a 7-day coach evaluation pass on its clubs page.[7]
- In ChessCore, the AI copilot drafts game review summaries, progress reports, parent recaps, and fee reminders; Stockfish supplies every position evaluation and a coach approves every send.
- Stockfish is a free, open-source chess engine and the strongest publicly available evaluator of chess positions, which is why drafts quote its output rather than the language model's opinion.[1]
- The NIST AI Risk Management Framework treats human oversight of consequential automated output as a core governance control, not an optional extra.[4]
- Student games enter the pipeline through the free Lichess API and read-only Chess.com import, so every rating number in a draft is verifiable on the player's public profile.[3]
- Approved parent updates are delivered over WhatsApp, the channel most academy families already check daily.[5]
- In the demo academy, Coach Priya reviews and approves a full batch of AI-drafted report cards in one sitting; previously each report was written by hand.
What can AI actually do for a chess coach today?
AI for chess coaches today is a set of named tool types, not one product: player-facing AI coaches such as BetterChess Club, workbook tools such as chessfeed.ai, and opening trainers such as AqylTap [7][8][9], plus academy management software such as ChessCore, whose AI copilot does the paperwork rather than the coaching [10]. BetterChess offers coached practice between club sessions [7], chessfeed.ai offers interactive study workbooks [8], and AqylTap offers opening assignments built from real games [9]. ChessCore's copilot drafts game reviews, progress reports, fee reminders and class recaps that wait in one queue for a coach or admin to approve [10]. Evaluation stays with an engine in both camps: BetterChess says its AI coach is grounded in a real chess engine [7], and ChessCore states that all chess evaluation comes from Stockfish and that the language model never judges a move [10].
Most discussion of AI chess coaching tools starts from the wrong end: can a model play well, explain openings, or replace a coach in front of a student? For an academy, those are the least interesting questions. The work that actually buries coaches is administrative writing. A coach with thirty students who wants to send monthly reports, weekly recaps, and a short note after each reviewed game is looking at hundreds of small documents a term. Each one needs accurate numbers, a sensible reading of recent games, and a tone the academy is happy to put its name on. That is exactly the shape of work where a language model assists well and where it fails dangerously if left unsupervised.
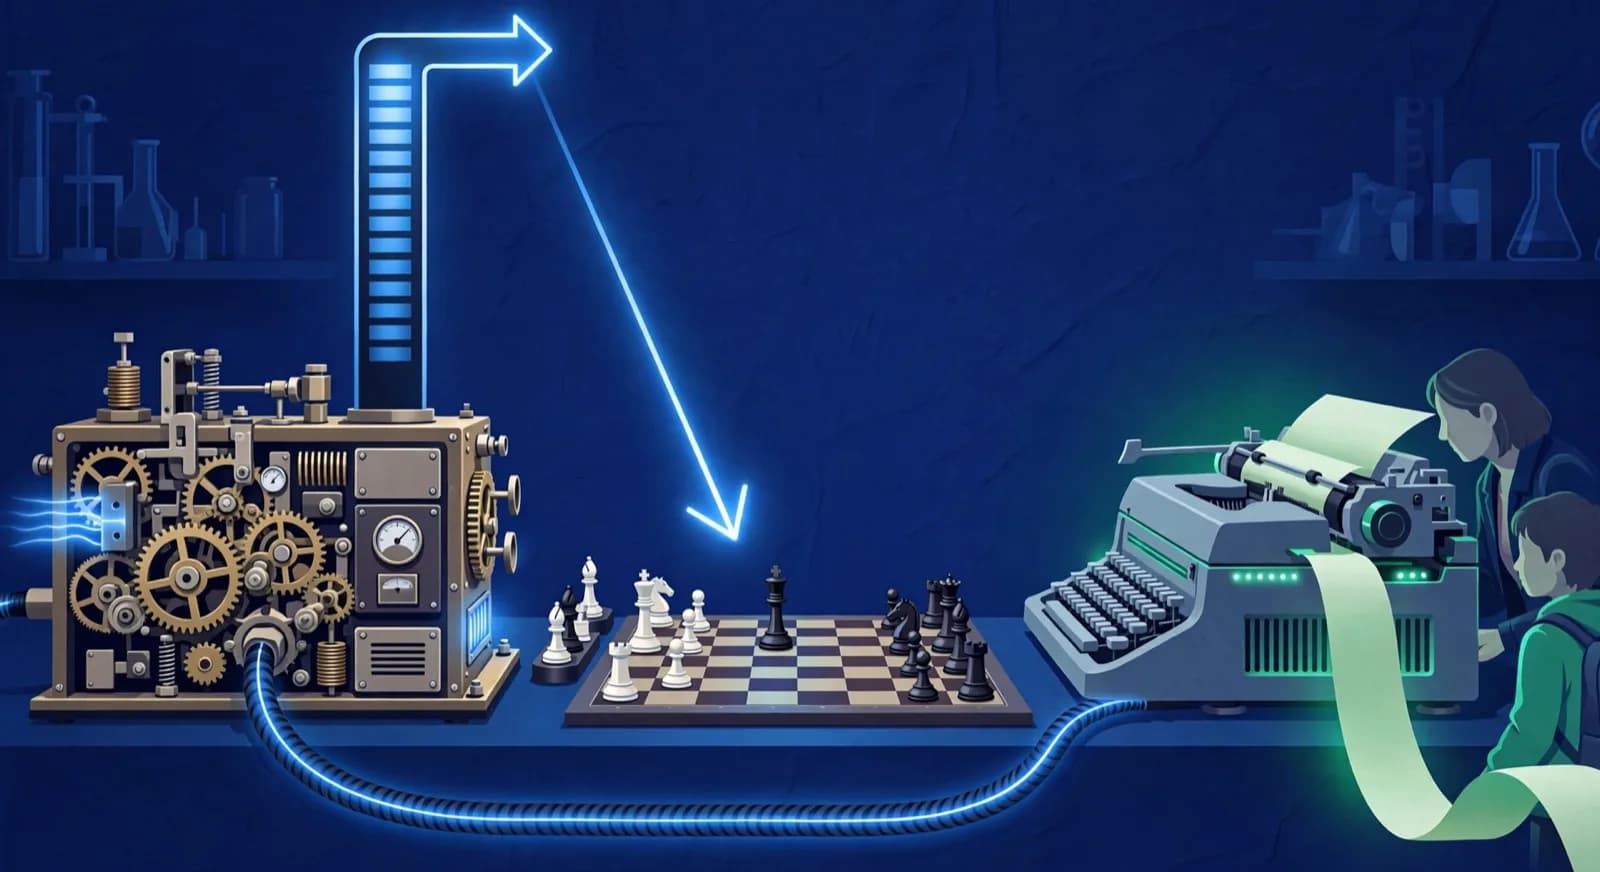
So the practical division of labor has four parts. The engine, Stockfish in our case, evaluates positions, because evaluation must be deterministic and reproducible [1]. The language model drafts narrative, because prose is what it is genuinely good at. The database supplies every number, because attendance, fees, and ratings already live in records and should never be re-imagined by a model. And a named human approves every send, because the academy's reputation rides on each message. Everything ChessCore's AI copilot does fits inside one of those four boxes, and we would argue any tool you evaluate should too.
The one-line test
If the task is writing from verified inputs, AI can draft it. If the task is evaluating a position, producing a number, or sending a message, a deterministic system or a human does it. Any AI feature that fails this test is a liability wearing a productivity costume.
What should the engine do and what should the language model do?
The engine evaluates; the language model explains. Stockfish, the open-source engine that has dominated computer chess for over a decade, searches millions of positions per second and returns the same evaluation for the same position every time [2]. A large language model does neither: it predicts plausible text, and a plausible-sounding evaluation of a chess position is frequently a wrong one. Keeping these two systems in their lanes is the single most important design decision in any AI chess coaching tool. Stockfish 18, released on 31 January 2026, is the current stable version, and it is free under the GPL [1][2].
In a well-built pipeline, the flow runs one way. Stockfish analyses a student's game and marks the moments that matter: the mistake on move 18, the missed tactic on move 24, the endgame technique that held a draw. The language model receives those engine-tagged moments plus the student's record and drafts a summary a parent or a twelve-year-old can read: what went well, what to work on, what the coach might assign as homework. The model never decides whether a move was bad; it is told, and it writes. Our comparison of engine analysis vs AI explanation walks through concrete examples of where each one fails alone.
Aarav R. vs. Diya K.
Rapid · synced from Lichess · Tue 7:42 PM
14...Qe6? drops the knight
Eval swings +2.1 · the move to review first
Missed fork on move 23
Same pattern as last Tuesday · drill it
Endgame conversion was clean
Won vs. 1410 · French Defense
Where do the numbers in AI drafts come from?
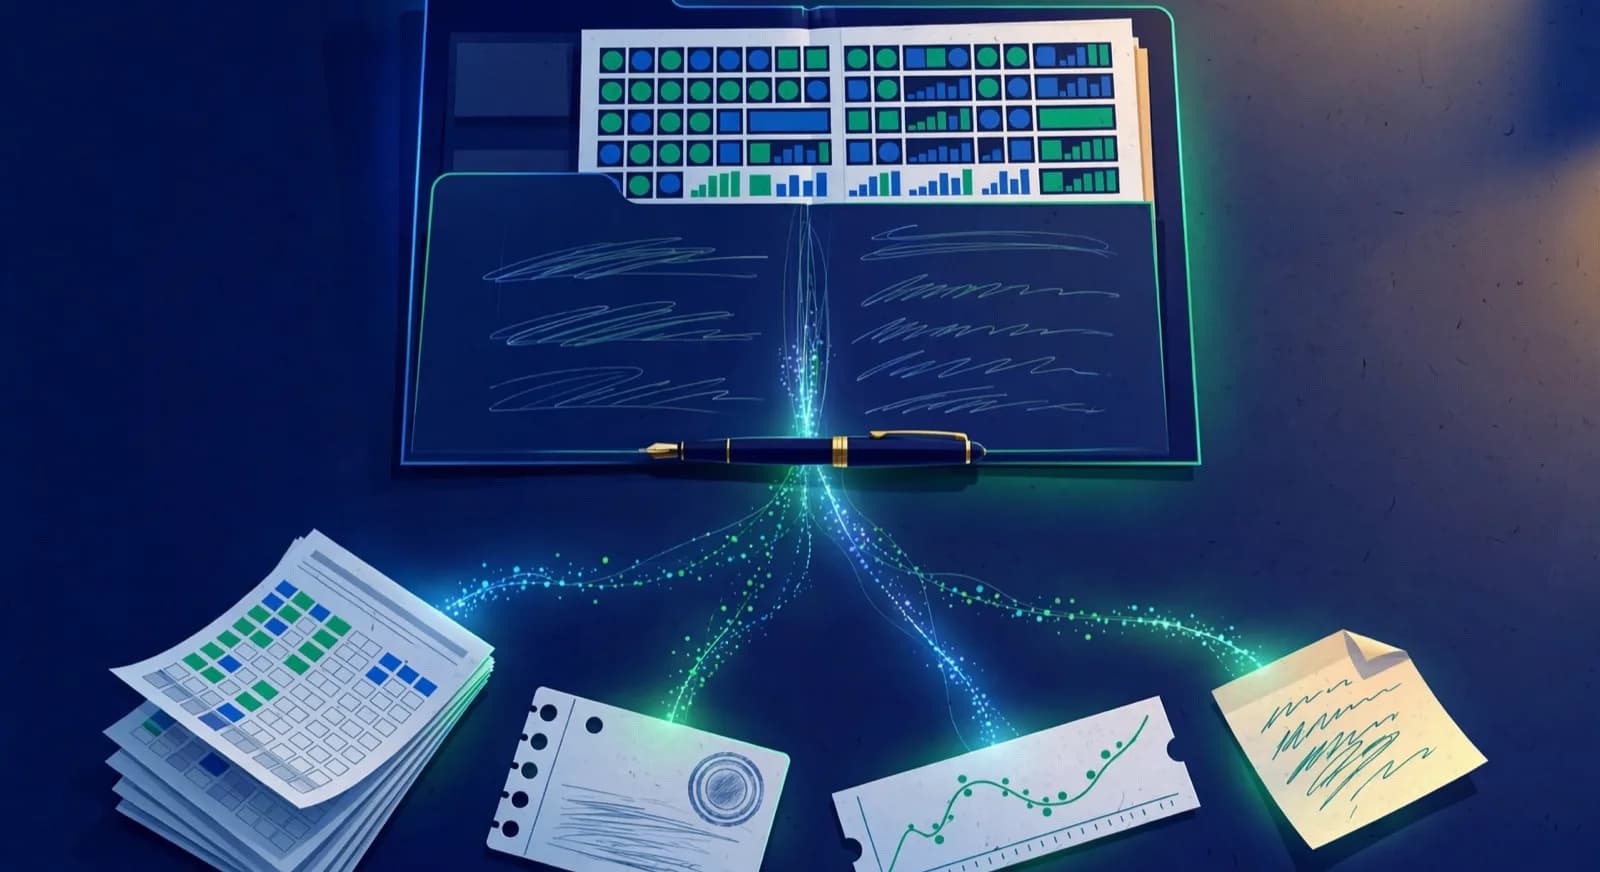
Every number in a draft should come from a database record, not from the language model. Attendance counts come from the attendance register, fee amounts from payment records, and rating figures from games synced through the Lichess API or imported read-only from Chess.com [3]. The model receives these values as fixed inputs and weaves prose around them; it has no ability to alter them, and in ChessCore the injected figures are highlighted in the draft so the reviewing coach can see at a glance which parts are locked.
This matters because a language model asked to recall or compute a number will happily produce one, and it will be formatted beautifully whether or not it is true. A parent who knows their child attended seven classes will not forgive a report that says eight, and a fee reminder with the wrong amount is worse than no reminder at all. The fix is architectural, not behavioural: do not prompt the model to be careful with numbers, deny it authorship of numbers entirely. In the demo academy, Aarav R.'s report shows a rating of 1395 after a +155 season because that is what his synced Lichess games show, and the ₹4,500 March fee in the Sharma family's reminder is read from the payment record that also generated their receipt.
Verifiability is the quiet benefit. Because rating numbers trace back to public Lichess or Chess.com profiles, a sceptical parent can check them, and a coach reviewing a draft never has to audit arithmetic, only judge prose. Our guide to AI guardrails in coaching software covers the wider set of controls; the number-injection rule is the one we consider non-negotiable in any tool, ours included.
Vendor question worth asking
Ask any vendor to show you, on screen, which parts of an AI draft came from records and which came from the model. If the product cannot make that boundary visible, the boundary probably does not exist.
Why must a human approve every message?
Because language models are probabilistic, their failure mode is a fluent draft that is confidently wrong, and parent-facing messages are exactly where that failure is most expensive. A human approval step converts AI from an autopilot into a copilot: the model proposes, the coach disposes, and the coach remains the author of record on every message the academy sends. The NIST AI Risk Management Framework, released as version 1.0 in January 2023 and now under revision, organises exactly this kind of control under its Govern function [4].
In ChessCore this takes the form of an approval queue: a single screen where every drafted report, game summary, recap, and reminder waits until a coach reads it, edits it if needed, and approves it. Nothing auto-sends, ever. We have written a full piece on why every AI message to a parent needs an approval queue, so we will not repeat the mechanics here; the short version is that review is minutes of reading where writing was hours, and the gate never opens on its own.
The channel raises the stakes. Approved updates go out over WhatsApp, because that is where families already are and where read receipts confirm delivery [5]. A WhatsApp message lands in the same thread as family conversation, which is precisely why no academy should let a model post there unsupervised. The trust you earn by being accurate in that thread compounds; one invented number discounts it instantly.
March progress report · Aarav R.
1 of 14 drafts for Batch B2
Aarav attended 11 of 12 classes this month and played 18 rated games, moving from 1348 to 1395.
His endgame conversion improved clearly. Next month the focus is back-rank defense, based on the mistakes tagged in his last three games.
Highlighted numbers come from your attendance and rating records. The AI cannot change them.
Goes to the Sharma family after approval
What does a coach check before approving an AI draft?
Six things, in this order: every number against the record it came from, the claim about the game against what the engine actually showed, the tone against the family it is going to, the omissions, the name on the message, and the send list. That order mirrors where errors actually hide and how long each check takes.
The list deliberately starts with the cheapest failure to catch. A wrong number is binary and quick to verify, while tone needs context and takes longer. Working from factual to judgmental keeps review fast without skipping the hard part.
- 1Every figure against its source record. Open the attendance register, fee record, or synced game and compare. Numbers are the only thing in a draft that can be proven wrong in seconds.
- 2Every claim about the game against the Stockfish-tagged moments. If the draft says the student missed a tactic on move 24, the engine line on move 24 should show it.
- 3Tone against the specific family. A direct nudge that motivates one parent lands as harsh to another. Read the draft as that family would, not as a generic reader.
- 4What the draft left out. The model only knows what you gave it. If a student showed real effort despite a loss, and the draft does not mention it, add it.
- 5Names, batch, and sender identity. Student, parent, batch, and the coach signing the message all have to match the record and the thread.
- 6Send list and channel. Confirm the draft goes only to families who should receive it, through the right thread, and that no fee reminder is queued for a family that already paid.
How to run the list
Print the list or keep it beside the approval queue. The number checks are fast because they are binary. The engine check is where overpraise gets caught. Tone and omissions are where the review time actually goes.
What goes wrong with AI-drafted coaching messages, and how do you catch it?
Five failure modes recur: a wrong number, praise the result does not support, tone that misreads a family, a stale rating from a sync that did not run, and a reminder sent to someone who already paid. Each has a specific detection step.
These follow from how the tools work, not from anecdote. They follow from how a language model works: it predicts plausible text given the prompt, it does not recompute ratings, and it has no memory of yesterday's payment unless the record is in the prompt. The table pairs each failure with its mechanism, the catch, and the owner so a coach can use it on Monday without buying anything.
Ownership is the column coaches skip and then regret. The first three rows sit with the approving coach because they require judgment about games and families. The last two sometimes need the person who runs the sync or the ledger, which is why the list matters: it tells you whom to ask, not just what to check.
What does an AI-assisted coaching week look like?
Mapped onto a real week, the framework looks unremarkable, which is the point. Take the demo academy's Batch B2, which meets Tuesday and Thursday under Coach Priya. After Tuesday's class, students play their assigned games on Lichess; the games sync automatically overnight through the Lichess API [3]. By Wednesday morning, Stockfish has analysed each game and the copilot has drafted a short review summary per student: the critical moment, what the engine showed, and a suggested focus for Thursday. Priya reads the drafts with her morning coffee, edits two where the model overpraised a lucky win, approves the batch, and the summaries land in each family's WhatsApp thread before lunch. The reviewing took her about fifteen minutes. Writing the same summaries by hand used to be the kind of task that quietly stopped happening by week four of term.
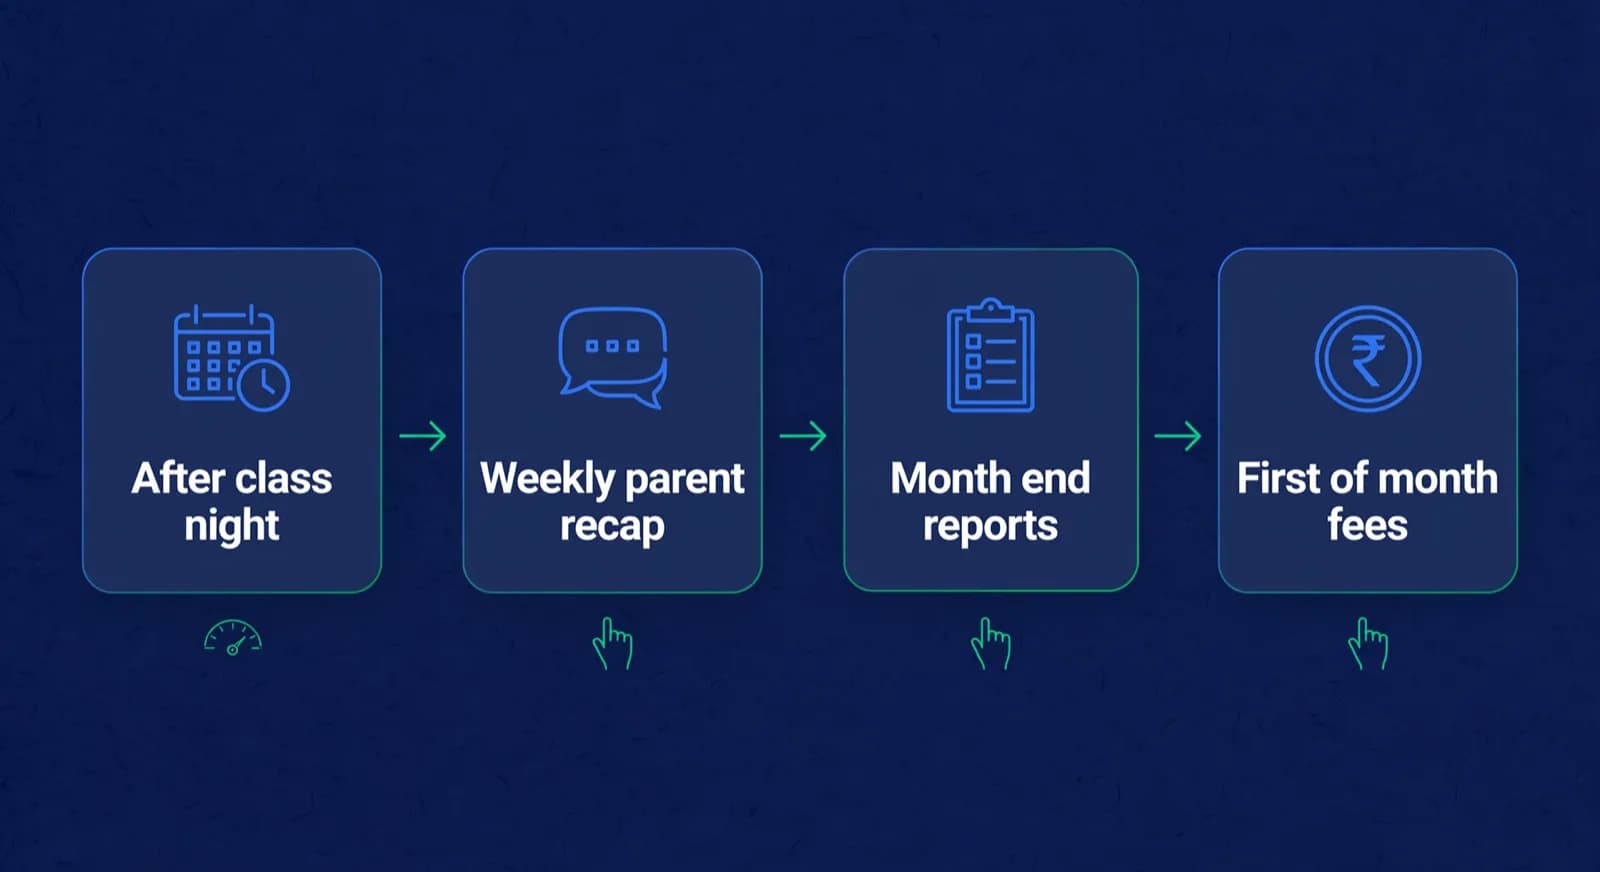
The monthly rhythm follows the same shape at larger scale. At month end, the copilot assembles a progress report per student: attendance from the register, rating movement from synced games, fee status from payment records, and a narrative drafted around the term's reviewed games. Aarav R.'s report notes his climb to 1395, a +155 season, because his games say so; the narrative around the number is the model's draft and Priya's judgment. She reviews the batch in one sitting, rewrites the paragraph for one student whose effort deserved more credit than his results, and approves. Our deeper guide to AI-drafted progress reports covers the report structure itself; what matters here is the cadence: reports now happen every month because the marginal cost of producing them collapsed.
Money runs on the same rails with even less drama. On the first of the month, fee reminders are drafted from payment records, each with the exact amount owed and a payment link; the ₹4,500 reminders go only to families with an open balance, and receipts go out the moment a payment lands. The academy holds 96% collection this term, and the operationally interesting part is what the AI does not do: it does not decide who gets chased, how firmly, or whether the Sharma family's request to split a payment is acceptable. Those are judgment calls, and they stay with a human.
Notice what never appears in this week: the model evaluating a position, the model inventing a figure, the model sending anything. Also notice what the coach never does anymore: stare at a blank page. Priya's actual coaching hours, lesson planning, in-class teaching, and the over-the-board conversation where she explains why a knight belongs on d5, are untouched. The AI did not make her a better coach; it gave her back the evenings that administrative writing used to take, and every word that reached a parent passed through her hands first.
What stays human, permanently
Lesson plans, in-class teaching, judgment about a student's effort and attitude, every decision about money flexibility, and the approve button. If a tool offers to automate any of these, that is a reason to walk away, not a feature.
How do you set this up if you do not use ChessCore?
Keep the four boundaries and change the tools: a real engine for evaluation, a spreadsheet or your existing records as the only source of numbers, a model that receives those values rather than recalling them, and one named person who approves every send.
A concrete setup that respects those boundaries looks like this. Run Stockfish locally or through Lichess analysis to get engine evaluations for each student game, then export the key moments (mistake on move 18, missed tactic on move 24) as short tags. Keep attendance, fees, and ratings in a sheet or your current system and export the exact figures you need for the batch. Build a prompt that pastes those tags and figures as fixed values and instructs the model to write around them without altering them. Generate drafts into a shared folder or doc, not into WhatsApp. One coach, named on the rota, reads each draft against the six checks above, edits, and then pastes the approved text into WhatsApp manually.
Three details make this work without extra software. First, never ask the model to recall or compute a number. If a number is not pasted into the prompt, the draft should not contain it. Second, keep the engine output visible to the reviewer. Even a simple line like Stockfish eval +2.3 on move 24 lets the coach spot overpraise. Third, separate draft time from send time. Payment records especially go stale between overnight generation and morning approval, so re-filter money messages against the ledger right before sending. The NIST AI Risk Management Framework, released as version 1.0 in January 2023 and now under revision, organises exactly this kind of control under its Govern function [4], but the operational version is simpler: no message leaves unless a person with their name on it said so.
What you do not need
No new platform, no agent that runs overnight, no model that evaluates positions. A free engine, the records you already keep, a standard language model, and a disciplined approval step are enough. The cost is reading time, not licensing, and the gain is the same as with any vendor: administrative writing stops being the bottleneck.
What are the best AI tools for chess coaches, and what do they cost?
The best AI for chess coaching, in our editorial view, is the tool that matches the job: BetterChess Club for student practice between sessions [7], chessfeed.ai for interactive workbooks [8], AqylTap for opening prep from real games [9], and ChessCore when the job is game reviews, progress reports and fee reminders that a coach approves before they reach a family [10]. There is no single winner across those jobs. Rank them by what you need this term, then check each seller's own page before you pay.
1. BetterChess Club
BetterChess Club is a player-facing AI coach sold to clubs and academies. As of 2 October 2026, its clubs page lists $99 per month for 25 student seats, extra seats at $3 per month, a free coach account, and a 7-day coach evaluation pass that is a single coach account, not a free trial of student seats [7]. For 40 students the sum works out as $99 plus 15 extra seats at $3 equals $144 per month.
2. chessfeed.ai Academy
chessfeed.ai Academy is built around an interactive study workbook: its academy page says coaches can combine positions, branches, notes, practice tasks, Opening Lens guidance and coach explanations in one workbook, then review how a student thought through the position, and it pitches its entry plan at academies starting with AI-supported review and coaching [8]. As of 2 October 2026, the academy page lists prepaid monthly plans per paid seat: Academy Essential at 899 rupees per paid seat per month (60 credits and 30 included game reviews) and Academy Plus at 1,299 rupees per paid seat per month (100 credits and 60 included game reviews). The page says self-serve academy account creation is not available and points new academies to a demo or to chessfeed.ai directly.
3. AqylTap
AqylTap is an opening trainer and AI game-analysis tool for coaches. Its homepage (October 2026) says coaches use the preparation module for free and only students who need assignments pay [9]. Published student plans on that page are Free at $0 with 2 searches per month, Premium at $10 with 20 PGN searches per month and a 10-day free trial, and Grandmaster at $100 with 250 PGN searches per year. It analyses Lichess and tournament games, measures opening depth, and turns mistakes into assignments.
4. ChessCore, academy ops copilot
ChessCore is academy management software with an AI copilot under human approval, not a player-facing AI coach. Stockfish produces every engine evaluation, numbers in drafts come from records, and nothing reaches a family until a coach or admin signs off [10]. For plan prices, see ChessCore's pricing page.
How much do AI coaching tools for clubs cost? Quote only what the seller's own page states on the day you check. BetterChess Club's listed package is $99 per month for 25 seats and $3 per extra seat, so 40 students is $144 per month on that page [7]. chessfeed.ai's academy seats are listed at 899 and 1,299 rupees per paid seat per month [8]. AqylTap's listed student plans start at $0 and list $10 and $100 options [9]. Recheck each official page before you budget, because vendors change limits.
Both categories can coexist in one academy. A coach might assign BetterChess or AqylTap practice while running reports and parent communication through management software. If you are surveying the player-facing side, the roundup of the best AI tools for chess academies compares categories with explicit criteria. The filter to carry into any of those evaluations stays the same: who evaluates, who writes, where numbers come from, and who approves.
Frequently asked questions
What are the best AI chess coaching tools for an academy?
Rank by job, not by a single score. BetterChess Club is a player-facing AI coach with a club package of $99 per month for 25 seats and $3 per extra seat on its clubs page [7]. chessfeed.ai Academy sells interactive study workbooks with AI-supported review and coaching, on prepaid seats at 899 and 1,299 rupees per paid seat per month [8]. AqylTap is an opening trainer whose homepage says coaches use the preparation module for free [9]. ChessCore is academy management software whose AI copilot does the paperwork, not the coaching, and its drafts wait for a coach or admin to approve [10]. Confirm each figure on the seller's own page before you buy.
Can AI replace a chess coach?
No. AI cannot run a lesson, judge a student's effort, or carry the relationship with a family, and a language model cannot even evaluate positions reliably; that is Stockfish's job. What AI replaces is the administrative writing around coaching: game review summaries, progress reports, parent recaps, and fee reminders, all drafted for a human coach to review and approve. The coach's actual coaching hours are untouched.
How does AI for a chess academy get student game data?
Through platform integrations rather than manual entry. ChessCore syncs student games from Lichess through its free public API and imports games read-only from Chess.com. Stockfish then analyses the synced games, and rating numbers quoted in any draft trace back to the student's public profile, so parents and coaches can verify them independently.
Is it safe to let AI send messages to parents?
Only if no message sends without a named human approving it. Language models occasionally produce fluent drafts that are confidently wrong, and a wrong rating or fee amount in a family's WhatsApp thread costs trust that is slow to rebuild. The NIST AI Risk Management Framework treats human oversight of consequential automated output as a core control, and an approval queue is the practical implementation of that control in coaching software.
Do AI chess tools evaluate positions themselves?
Well-built ones do not. Evaluating positions is the engine's job: Stockfish is deterministic, reproducible, and verifiable against the PGN, while a language model asked to judge a position produces plausible text that is frequently wrong. In a sound pipeline the engine tags the critical moments and the language model only writes the explanation around evaluations it is handed.
What is the best AI for chess coaching?
There is no single best AI for chess coaching; these picks are our editorial view. Choose BetterChess Club when you want every student to get coached practice between sessions [7], chessfeed.ai when you want interactive workbooks [8], AqylTap when opening prep from real games is the bottleneck [9], and ChessCore when the job is game reviews, progress reports and fee reminders a coach must approve before a family sees them [10]. On engine work, BetterChess says its coach is grounded in a real chess engine [7], and ChessCore says Stockfish judges every position while the language model only writes the prose [10].
Sources
- [1]Stockfish: strong open-source chess engine · accessed 2026-08-12
- [2]Stockfish (chess) on Wikipedia · accessed 2026-08-12
- [3]Lichess.org API documentation · accessed 2026-08-12
- [4]NIST AI Risk Management Framework · accessed 2026-08-12
- [5]WhatsApp Business · accessed 2026-08-12
- [6]Chess.com Published-Data API · accessed 2026-08-12
- [7]BetterChess Club: AI coaching for clubs · accessed 2026-10-02
- [8]chessfeed.ai Academy software and workbooks · accessed 2026-10-02
- [9]AqylTap: opening trainer and AI game analysis for coaches · accessed 2026-10-02
- [10]ChessCore AI copilot: drafts under human approval · accessed 2026-10-02
Written by Abhishek Tiwari
ChessCore
Drafted with AI, fact-checked and approved by a human before publishing, the same guardrail our product applies to every report it sends. Read our editorial standards.
Watch the division of labor run on your data
Bring one batch's games and records to a walkthrough: Stockfish analyses, the copilot drafts, your numbers stay locked to records, and your coach approves every send.